

Introduction
Base44 belongs to a newer class of AI products that blur the boundary between a no-code app builder, an AI website builder, and a software-development agent. Instead of generating only a mockup or a few frontend components, it is designed to take a plain-language description and build much of the application around it: screens, data structures, backend functions, authentication, permissions, integrations, hosting, and deployment. Base44’s own AI app builder page describes the goal as moving from prompt to a functioning product rather than stopping at a prototype.
That distinction is important in a review focused specifically on Base44 UI/UX and web design. A system can be exceptionally efficient at turning a business requirement into a usable application without necessarily producing the most refined visual design in a competitive field. Base44 is trying to solve both sides of the problem, but its all-in-one development workflow is central to the product.
Base44 was founded by Maor Shlomo in late 2024. The project began as a small, bootstrapped operation and grew unusually quickly. By the time Wix announced its acquisition in June 2025, TechCrunch reported roughly 250,000 users, while Wix said Base44 would continue operating as a distinct product and business. Wix disclosed approximately $80 million in initial consideration, plus performance-linked earn-out payments through 2029.
The latest user figure we could verify is considerably larger. A Crusoe case study dated September 17, 2026 states that Base44 had passed 10 million users. That source calls them “users”; it does not establish that all 10 million were active users, paying customers, or subscribers, so we do not relabel the metric. Find Premium AI evaluated Base44 for a narrower question: how well does it perform as an AI tool for UI/UX & Web Design? Our latest six-product hands-on evaluation was finalized on October 1, 2026. The ranking was not predetermined, Base44 was not selected for preferential treatment, and public customer scores did not determine the outcome by themselves. Our overall scores reflect our own testing methodology and factor weights. Another research team especially one emphasizing different priorities could reasonably reach a different ordering.
For that reason, the most useful way to read our Base44 score is not as a universal verdict. It is a measurement of how the platform performed under the particular requirements we consider important for AI-assisted UI/UX and web-design work.
Performance
Base44’s real advantage is how much it builds at once
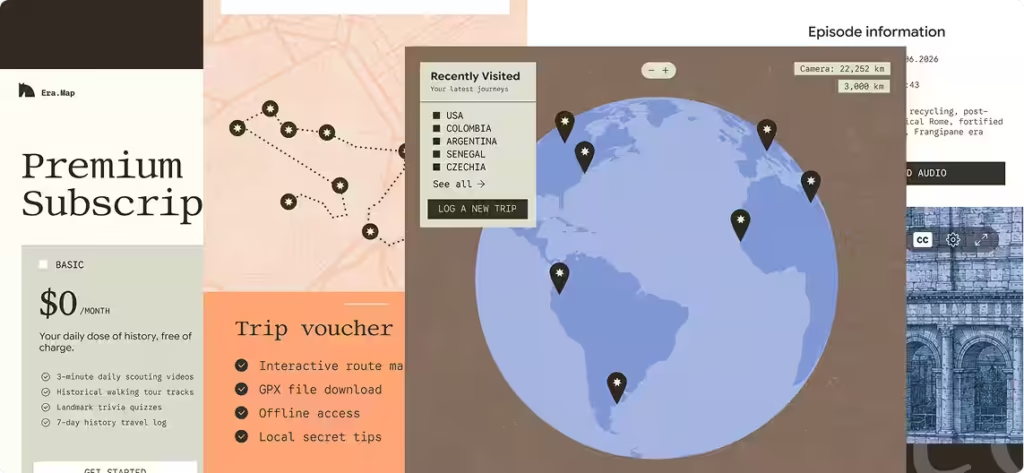
The appeal of Base44 becomes obvious once a project extends beyond a landing page. Its current product can generate interface screens while also creating the data layer, authentication, roles and permissions, backend logic, integrations and deployment environment needed to make those screens useful. Hosting is built in, and Base44 also offers custom domains, visual refinement, analytics, application testing, and security scanning. In June 2026, the company introduced a production-oriented package containing Verification, a Testing Agent and Security Scan, while its current product documentation describes automatic security scanning as part of the broader application-building workflow.
That breadth is why Base44 is particularly effective for a certain kind of UI/UX project: not a static marketing concept, but a CRUD or workflow application where users need to sign in, create or update data, move through states, and interact with business rules. Think of an internal operations portal, customer dashboard, lightweight CRM, scheduling tool or approval system. In a traditional workflow, the visual interface, database, permissions, APIs, backend logic and deployment could involve several tools or specialists. Base44 can put much of that work into one conversational environment.
Our hands-on testing therefore points to a clear best-fit profile: a solo founder, small business, or internal team that wants authentication, data, permissions, application logic and hosting in one place. That does not automatically make Base44 the stronger choice for a designer whose primary concern is nuanced typography, bespoke interaction design or strict design-system fidelity. Those priorities showed up differently in our scores.
Prompting, iteration and visual control
Base44’s AI environment is more agentic than a conventional “generate this page” interface. Its documentation describes three principal working modes: Build acts on an instruction immediately. Discuss lets the user plan or clarify a change without modifying the application until it is approved. Edit allows direct visual selection and adjustment of elements in the preview. The AI can inspect files, work with the database, search for relevant information, modify project files and examine logs as part of a task.
That separation is useful in UI work. It reduces the need to make every adjustment through a fresh full-page prompt. In Edit mode, for example, users can manually change colors and spacing or open an element’s code and adjust Tailwind classes for typography, layout and responsive behavior. Manual visual edits do not consume message credits; asking the AI to make the same edit does. Version History also provides a way to restore previous states. In our testing, this produced a workflow that felt fastest when the intended interface could be described in product terms: “build a dashboard with these records, these permissions and this workflow.” The product was less convincing when the objective became highly art-directed visual design for its own sake. That difference appears in our results. Base44 scored 8.3 for Speed, one of its stronger categories, but 7.7 for UI/UX and web-design quality.
Base 1: what Base44 actually built, and what it did not
Base44’s underlying AI deserves careful treatment because describing Base 1 simply as a proprietary frontier model would overstate what has been publicly established. On June 29, 2026, Base44 announced Base 1, its first in-house model aimed specifically at application creation. Founder Maor Shlomo described it as a model optimized around the repeated engineering, product and design decisions that occur inside Base44.
Independent reporting provides the important technical qualification: CTech reported that Base 1 was developed and fine-tuned in-house on top of an existing open-source foundation model. Shlomo explicitly contrasted that approach with training a frontier foundation model entirely from scratch. The company has not publicly identified the exact upstream open-source foundation model in the material we could verify, so naming one would be speculation.
Base44 also remains a multi-model platform. Its current documentation offers automatic model routing, Base 1 and third-party models. Users on Builder or higher can choose a model manually, and the system can run the same instruction through two different models for side-by-side comparison. That comparison consumes twice the credits because it generates two versions.
The distinctions are therefore:
Base 1 is Base44’s own specialized model, built by fine-tuning an existing open-source foundation model. Third-party frontier models remain available within the Base44 platform. Base44 itself supplies the broader agent, application architecture, editing environment, backend, hosting and deployment system in which those models operate. That architecture matters more to a buyer than attaching all of Base44’s performance to a single model name.
What independent testing says about Base 1’s design sense
A useful outside data point came from a July 2026 Business Insider test comparing Base 1 with Anthropic’s Opus 4.8 inside Base44. The journalist gave both models the same prompt for an e-commerce site without prescribing the visual style. Base 1 generated a more distinctive deep-blue design with bright yellow accents, whereas the Opus version followed a more familiar light/beige AI-generated aesthetic. Base 1 also completed the initial task faster in that particular comparison.
The result should not be turned into a broad benchmark. The test involved one website and one prompt. Business Insider also found familiar signs of AI-generated design in Base 1’s output, including rounded cards and substantial emoji use, and concluded that the two systems were otherwise fairly similar. On a follow-up modification, Base 1 completed the task faster and consumed 1.2 credits versus 1.4 for Opus. That qualitative evidence is consistent with our own more cautious assessment: Base44 can produce visually credible work quickly, and Base 1 shows signs of trying to escape generic vibe-coded styling, but visual distinctiveness is not yet consistently strong enough to erase the need for designer intervention.
Figma import helps, but does not remove the refinement stage
Base44 can also start from an existing Figma design rather than a text prompt. Its Figma import documentation allows a frame to become the foundation for a new Base44 app or a new page in an existing project. The system attempts to recreate the frame’s layout, structure and visual styling and can then extend the design language into additional pages.
There are real limitations. Base44 says only Google Fonts are fully supported during import; unsupported custom fonts are replaced. Multiple fills, some image effects and variable-driven styles may not transfer exactly. Its documentation explicitly recommends refining spacing, responsive behavior and interactions after import. That makes Figma import useful as a bridge between conventional product design and AI development, but not a substitute for checking the implementation. For teams with an established design system, the quality of the Figma file itself clean frames, sensible Auto Layout and consistent spacing also affects the result.
Responsive design and moving toward production
Base44’s visual workflow supports responsive adjustments rather than limiting the user to a static desktop canvas. Tailwind classes can be edited manually, and Base44’s Figma guidance emphasizes layout structures that resize predictably. Its standard plans also include a responsive visual editor.
Once the interface is functional, the same project can move toward deployment without being rebuilt elsewhere. The platform includes web hosting and production infrastructure, while authentication, user management, database functionality and integrations remain attached to the project. This is a major advantage for prototypes that need to become usable internal or customer-facing applications quickly. It is also where the platform’s main architectural trade-off becomes important.
Portability has improved, but Base44 is still a managed platform
Base44 now offers significantly more code access than an older-style closed no-code builder. On Builder and above, two-way GitHub integration lets an owner connect a repository, clone the project locally, edit it in a normal development environment and synchronize changes back to Base44. The company’s pricing page goes further and says users own their code, data and users, while its Terms of Service state that, as between Base44 and the customer and to the extent such rights exist under applicable law, the customer owns the generated code and applications. Commercial use is also permitted under its terms.
But “you can export the source” and “the platform is identical to a repository-first development stack” are not the same claim. Base44’s own local-development documentation requires the Base44 CLI; local development starts a Base44 backend alongside the frontend, while remote mode runs the frontend against the live Base44-hosted backend. The SDK documentation also says that service-role authentication is available only inside Base44-hosted backend functions. An external frontend can use Base44 through its SDK, but it is still using Base44 as a backend service.
Our interpretation is therefore more nuanced than simply calling it “locked in.” Portability is materially better than a closed no-code platform, but Base44 remains more managed and less infrastructure-independentthan a conventional repository-first application. For a founder who values speed, that can be a perfectly sensible trade. For an engineering team whose priority is complete deployment portability, infrastructure ownership or swapping backend services freely, it deserves consideration before a large application becomes deeply dependent on the platform.
Complex logic remains the bigger risk
The other major limitation we found was less predictable behavior as application logic became more complicated. This concern is not based solely on our testing. Public feedback repeatedly raises issues around AI-generated errors, repeated attempts to fix the same problem and credit consumption during debugging. Base44’s own documentation confirms that it does not provide credit reversals for AI actions that produce mistakes; users can revert a change, but the credits consumed by the action are not automatically restored.
That dynamic matters because a visually small fix can turn into a costly iteration loop if the underlying problem spans data, state, permissions or backend behavior. For relatively conventional CRUD and workflow applications, Base44’s abstraction is a strength. For intricate application logic, unusual infrastructure requirements or systems where developers want precise control over every implementation decision, the abstraction can become a constraint.
The seven factors behind our Base44 score
Before comparing Base44 with the other five products, it helps to understand what our seven factors measure. Our weighting deliberately gives the largest share to UI/UX and Web-Design Quality (25%) and Prompt Accuracy (20%). Speed matters, but producing an interface quickly is not enough if substantial design correction or requirement repair is still necessary.
| Evaluation Factor | What It Measures | Weight |
|---|---|---|
| AI Intelligence | Architectural reasoning; repository and design-system understanding; context retention; debugging; tool selection; multi-step planning; recovery after failed approaches. | 15% |
| Speed | Time and consistency from request to an accepted runnable result, including latency, retries, tool efficiency, tests, and revision time. | 10% |
| UI/UX and Web-Design Quality | Visual hierarchy; typography; spacing; color; responsive behavior; interaction states; accessibility/semantics; design-system fidelity; information architecture; originality and polish. | 25% |
| Prompt Accuracy | Requirement coverage; literal adherence; scope discipline; handling of ambiguity; preservation of existing behavior; quality of follow-up revisions. | 20% |
| User Rating | Weighted public satisfaction from credible review platforms | 10% |
| Review Confidence | Authenticity/verification; sample size; relevance to the current product/version; recency; source diversity; agreement or divergence between platforms. | 5% |
| Features & Usability | Onboarding; visual editing; code/repository control; design-system and Figma import; backend/integrations; testing; deployment; collaboration; accessibility; plan limits and portability. | 15% |
The pattern is more informative than the overall number. Base44’s strongest proposition is fast, integrated product creation. Its limitations appear more clearly in high-end visual refinement, complex logic and the trade-offs of working inside a managed full-stack environment.
Comparisons Before You Buy
Our six-company ranking reflects Find Premium AI’s hands-on research completed on October 1, 2026. It should not be interpreted as an industry-wide ranking or a claim that the first product will be preferable for every buyer. We tested the same broad use case AI-assisted UI/UX and web design but the seven factors do not all have equal weight. A professional product designer who values visual fidelity above everything else could reasonably choose differently from a founder who mainly wants the fastest route to a functioning application.
Our finalized results were:
| Product | Overall Score | AI Intelligence | Speed | UI/UX & Web Design Quality | Prompt Accuracy | User Rating | Review Confidence | Features & Usability | Best For |
|---|---|---|---|---|---|---|---|---|---|
| v0 by Vercel | 8.95 | 9.2 | 9.2 | 8.7 | 9.2 | 9.8 | 6.0 | 9.0 | Frontend teams shipping polished Next.js products |
| Lovable | 8.79 | 8.8 | 8.4 | 9.0 | 8.5 | 9.4 | 7.5 | 9.1 | Teams building polished managed-backend SaaS products |
| Figma Make | 8.55 | 7.6 | 7.8 | 9.6 | 8.8 | 9.5* | 4.5 | 8.6 | Figma-driven product prototyping teams |
| Replit Agent | 7.96 | 8.7 | 7.6 | 7.2 | 7.4 | 9.2 | 7.5 | 8.8 | Engineers, students, and teams that want a browser-based repository |
| Base44 | 7.91 | 7.7 | 8.3 | 7.7 | 7.8 | 8.8 | 6.0 | 8.4 | A solo founder, small business, or internal team building a workflow application |
| Bolt.New | 7.65 | 7.8 | 6.5 | 7.8 | 7.0 | 8.8 | 6.5 | 8.5 | JavaScript teams building fast hosted prototypes |
*Our Figma User Rating benchmark used professional feedback for the broader Figma product rather than treating it as a standalone Figma Make customer-review score.
Base44 ranked fifth in our October 1, 2026 hands-on evaluation with an overall score of 7.91. That position needs context because some of the numerical gaps are very small. The closest comparison is Replit Agent. Replit’s 7.96 overall score was just 0.05 points higher than Base44’s. Replit performed materially better in AI Intelligence, 8.7 versus 7.7, and slightly better in Features & Usability, 8.8 versus 8.4. Base44 went the other direction on Speed, 8.3 versus 7.6, UI/UX quality, 7.7 versus 7.2, and Prompt Accuracy, 7.8 versus 7.4.
That is a good example of why ordinal rank alone is not enough. Someone building a conventional business workflow quickly could value Base44’s combination of speed, backend and managed deployment more than Replit’s stronger reasoning result. A developer working across a deeper engineering workflow could reach the opposite conclusion.
Bolt.New finished at 7.65, 0.26 points below Base44 overall. Base44’s clearest advantage was Speed—8.3 against 6.5—and it was also ahead in Prompt Accuracy at 7.8 against 7.0. Bolt.New nevertheless edged Base44 in UI/UX quality, 7.8 versus 7.7, and Features & Usability, 8.5 versus 8.4. Buyers who care more about those two categories than our weighting does should not dismiss Bolt merely because it finished sixth.
Figma Make illustrates the opposite trade-off. Its 8.55 overall score was 0.64 points above Base44, and its 9.6 UI/UX score was the highest result in the comparison. Base44 was faster 8.3 to 7.8 and slightly higher in AI Intelligence, 7.7 to 7.6, but UI/UX quality carries 25% of our methodology. A designer prioritizing visual fidelity therefore has a concrete reason to care about Figma Make even if Base44 offers a more integrated path to application logic and hosting.
Lovable scored 8.79. It was ahead of Base44 in every measured category except that their Speed scores were close: 8.4 for Lovable versus 8.3 for Base44. In our testing, Lovable’s stronger 9.0 UI/UX quality, 8.8 AI Intelligence, 8.5 Prompt Accuracy and 9.1 Features & Usability created a clearer advantage for teams seeking a polished managed full-stack workflow.
v0 by Vercel ranked first at 8.95, 1.04 points above Base44. Its largest advantages were in AI Intelligence and Prompt Accuracy, both 9.2, compared with Base44’s 7.7 and 7.8. It also scored 9.2 for Speed and 8.7 for design quality. The latest Product Hunt data still shows v0 at 4.9 out of 5 from 60 reviews, which matches the public-review signal used in our research snapshot.
Base44 did not lead our six products in any one factor, but that does not make the profile uninteresting. Its 8.3 Speed was the third-highest speed result and substantially better than Replit Agent, Figma Make and Bolt.New. Its appeal is therefore less about category dominance and more about how much of the product-development stack it compresses into one experience.
Customer Reviews
We deliberately researched public opinion separately from our hands-on testing so that our own experience would not become the only source of evidence. For the scorecard itself, our researchers chose Product Hunt as the primary Base44 public-rating signal, recording 4.4 out of 5 from 41 reviews. That figure remains visible on the live Base44 Product Hunt page.
We prioritized Product Hunt not because 41 reviews constitute a particularly large statistical sample, but because the community is unusually relevant to this product category: it is heavily populated by software makers, founders and early adopters evaluating newly launched digital products. Product Hunt also publishes mechanisms for flagging false, spam, retaliatory or unethical reviews, and its community rules prohibit spam and artificial engagement. That improves the usefulness of the signal, although it is not the same thing as G2’s formal validated-reviewer process.
The 4.4/5 Product Hunt result should therefore be read as relevant but not conclusive. Our wider October 1 Base44 review study looked like this:
| Source | Rating recorded in our research | Review/rating count | How we treated it |
|---|---|---|---|
| Product Hunt | 4.4/5 | 41 reviews | Our primary public-review reference because of the product/maker audience and direct relevance to AI-building workflows. |
| Google Play | 4.0/5 | ≈1,700 reviews | Stronger volume for Android-app experience, but not a pure measure of the desktop/web builder. |
| G2 | 3.8/5 | 4 reviews | Individual professional-user feedback was useful, but the sample was far too small for a confident aggregate conclusion. |
| GetApp | 3.3/5 | 3 reviews | Verified software-buyer feedback, but again an extremely small sample. |
| Apple App Store, U.S. | 3.3/5 | 63 ratings | Relevant to the iPhone/iPad product; ratings do not necessarily represent written reviews or the browser builder. |
| Trustpilot — base44.com | 2.8/5 | 896 reviews | Much larger customer-experience sample and therefore impossible to ignore, but broader than UI/UX performance alone. |
| Trustpilot — app.base44.com | 2.5/5 | 5 reviews | Separate unclaimed subdomain listing with too little evidence for a broad conclusion. |
| SourceForge / Slashdot | 1.0/5 | 1 rating/review each | Far too little evidence to generalize. |
| Gartner Peer Insights | 5.0/5 | 1 rating | One positive enterprise rating cannot demonstrate consistent performance. |
Some live numbers have already moved slightly since that October 1 snapshot, which is exactly why we date the research. The main claimed Trustpilot profile showed 2.8 out of 5 from 898 reviews when rechecked on October 2, with 53% of reviews at one star. The site’s summary and recent reviews contain recurring complaints around unexpected AI errors, rapid credit use and support, alongside positive reviews praising simplicity and quick app creation.
That gap between 4.4/5 on Product Hunt and 2.8/5 on Trustpilot is significant. We do not think the responsible response is to choose whichever number supports a preferred conclusion. The populations are different. Product Hunt’s audience is unusually aligned with makers trying new software tools. Trustpilot captures much broader customer-service, billing and post-purchase experiences. A person may therefore rate the underlying concept and speed of Base44 highly on one platform while another customer’s evaluation is dominated by a billing issue, a support interaction or repeated production errors.
The mobile stores add another distinct population. Our October 1 snapshot recorded Google Play at about 4.0/5 from roughly 1,700 reviews. The current listing visible in our recheck reports 4.1 stars and approximately 1.66K reviews, reinforcing that Android sentiment is more positive than the main Trustpilot profile. Apple’s U.S. App Store has also moved around since our snapshot; the current page we retrieved showed 3.2 out of 5 with around 60 ratings. Reviews there include complaints about mobile bugs and workflow friction, so we treat the App Store primarily as evidence about the mobile experience rather than a direct proxy for Base44’s web builder.
GetApp currently reports 3.3 out of 5 from three reviews, while G2 shows 3.8 out of 5 from four reviews. G2 has a strong moderation methodology published reviews go through validation and manual moderation but four Base44 reviews remain too few for a robust aggregate signal. Gartner Peer Insights displays 5.0 from one rating, and SourceForge shows 1.0 from one review. Those opposite results demonstrate why tiny samples should not be allowed to dominate an assessment.
We also did not combine Capterra, Software Advice and GetApp counts where reviews may be syndicated across Gartner Digital Markets properties. Adding overlapping reviews together would create a false impression of independent evidence. This disagreement across sources is a major reason Base44 received only 6.0 for Review Confidence even though its User Rating factor was 8.8. We found meaningful positive sentiment, but the supporting evidence is less stable than it is for products with large, broadly consistent verified-review populations.
For context, the public sources selected in our October 1 comparison showed:
| Product | Source used | Public Rating | Votes & Reviews |
|---|---|---|---|
| v0 by Vercel | Product Hunt | 4.9/5 | 60+ reviews |
| Lovable | G2 | 4.6/5 | 433+ reviews |
| Figma Make | Trustradius | 4.4/5 | 1.7k+ reviews |
| Replit Agent | G2 | 4.4/5 | 413+ reviews |
| Base44 | Product Hunt | 4.4/5 | 41+ reviews |
| Bolt.New | G2 | 4.3/5 | 96+ reviews |
The underlying live pages still broadly support the relative public signals for v0, Lovable, Replit and Bolt: Product Hunt currently displays v0 at 4.9/5 from 60 reviews, G2 displays Lovable at 4.6/5 from roughly 434 reviews, Replit at 4.4/5 with more than 400 reviews, and Bolt.New at 4.3/5 from 96 reviews.
*The Figma figure in our scorecard is a benchmark based on professional Figma reviews, not a standalone Figma Make customer-review average. TrustRadius currently reports the broader Figma platform at 8.9 out of 10 from 1,739 reviews and ratings, which is another reason not to convert rating scales casually or present a parent-product score as though it were a dedicated Figma Make score. The public evidence does not “prove” our ranking. It does, however, reinforce why review confidence deserves its own factor rather than being folded blindly into a star average.
Pricing
Base44 currently offers Free, Starter, Builder, Pro, Elite and Enterprise tiers. The most important detail is that Base44 uses two types of usage allowance. Message credits are primarily consumed while building and changing an application through the AI. Integration credits are consumed by services used inside live applications, such as email actions, image generation, LLM calls and agents. Usage varies by task and model, and paid allowances reset with the billing cycle rather than accumulating indefinitely. Base44’s current pricing page and July 2026 pricing guide provide the following published prices and allowances.
| Plan | Monthly billing | Annual-billing equivalent | Credits per month | Main inclusions relevant to our testing |
|---|---|---|---|---|
| Free | $0 | $0 | 25 message + 100 integration | Up to five apps; authentication, database functionality and analytics |
| Starter | $20/mo | $16/mo equivalent ($192/year) | 100 message + 2,000 integration | Unlimited apps, in-app code editing, custom-domain connection; our plan testing also confirmed Base44 badge removal |
| Builder | $50/mo | $40/mo equivalent ($480/year) | 250 message + 10,000 integration | Builder-oriented backend functionality, two-way GitHub, manual AI-model selection; annual plan includes a free domain for one year |
| Pro | $100/mo | $80/mo equivalent ($960/year) | 500 message + 20,000 integration | Builder capabilities plus early beta-feature access and larger allowances |
| Elite | $200/mo | $160/mo equivalent ($1,920/year) | 1,200 message + 50,000 integration | Highest self-serve allowance plus premium support |
| Enterprise | Custom | Custom | Custom | Organization-level controls including SSO/SCIM, granular roles, audit and governance features, IP restrictions, custom capacity and dedicated support |
The current live pricing page confirms the self-serve credit amounts and the 20% annual-billing discount, while Base44’s Enterprise material documents SSO enforcement, SCIM provisioning, IP allowlisting, audit APIs, granular publishing permissions and dedicated enterprise support. The free plan is enough to understand the workflow but deliberately restrictive. Base44’s own student page describes the free allowance as five credits per day and 25 per month, which means an enthusiastic user can hit the daily ceiling well before the monthly total.
Our default purchase recommendation is therefore Starter on monthly billing at $20 per month for most individual builders.
That is a change from simply assuming that Builder is the default “serious” plan. Starter is the safer first purchase because it already gives an individual substantially more room to work, unlimited apps and practical production-facing features without requiring a $50 monthly commitment. Base44 itself says most creators land on Starter. More importantly, beginning month-to-month gives a buyer time to measure how many credits their real project consumes before committing to a year.
For a typical solo builder, the sequence we would use is straightforward: exhaust enough of Free to establish that the platform understands the project, move to Starter monthly while measuring real iteration and integration consumption, and only then decide whether a higher tier or annual commitment is justified. Builder becomes the more appropriate plan when the requirement is already clear: you need GitHub version control, manual AI-model selection, heavier integration usage, or a more developer-involved production workflow. Two-way GitHub sync and manual model selection both require Builder or above.
Pro and Elite make more sense when scale, credit consumption or support requirements not status justify them. Pro doubles Builder’s message allowance and integration capacity; Elite raises them to 1,200 and 50,000 respectively and adds premium support. Paying for those tiers before knowing the application’s actual usage pattern is difficult to justify. Annual billing is a genuine discount rather than a marketing comparison against a different product bundle. Base44 states that yearly billing saves 20% across Starter, Builder, Pro and Elite.
That means the straightforward annual savings are:
- Starter: $240 paid month-to-month versus $192 yearly, saving $48 per year.
- Builder: $600 versus $480, saving $120 per year.
- Pro: $1,200 versus $960, saving $240 per year.
- Elite: $2,400 versus $1,920, saving $480 per year.
The discount is real, but we would still choose monthly first for a new Base44 user. The main financial uncertainty is not the subscription arithmetic; it is whether a particular application will require repeated AI correction, heavy integrations or a workflow that eventually feels constrained by the managed environment. If those questions have already been answered through real use, the calculus changes. A builder committed to Base44 for the next year saves a clean 20% by paying annually. Builder annual at $480 is especially reasonable for a user who already knows they need GitHub, model selection and the larger credit pool.
Educational users have another option. Base44 currently advertises 50% off selected paid plans for students and educators. Its student program specifies 50% off a first Starter or Builder plan for verified students, for up to 12 months, while its higher-education page extends the education offer to students and educators. That can materially change the value calculation for an eligible academic user and is worth checking before subscribing at standard price.
Conclusion
Base44 makes the most sense when the interface is only one part of the problem. If you are a solo founder, small business or internal team building a data-driven workflow application, its combination of prompt-based development, authentication, permissions, database, backend logic, integrations, hosting and rapid iteration is unusually convenient. The platform removes a large amount of setup that has little to do with the business idea itself.
That advantage was visible in our 8.3 Speed score and 8.4 Features & Usability result. It was also visible in our hands-on workflow: Base44 could move from a requirement to something functional quickly because the front end did not need to wait for a separately assembled backend and deployment stack. Where Base44 becomes less convincing is when visual sophistication, infrastructure independence or complicated logic becomes the dominant requirement.
Its 7.7 UI/UX and web-design quality score trailed Figma Make at 9.6, Lovable at 9.0, v0 at 8.7 and Bolt.New at 7.8 in our testing. Base44’s visual tools, Figma import and Base 1 model have improved the design side of the product, and Business Insider’s one-off comparison suggests Base 1 can produce a less generic palette than a general-purpose frontier model in some circumstances. But even that test still found recognizable vibe-coded patterns, and our broader testing did not show consistently top-tier visual polish.
Its 7.7 AI Intelligence and 7.8 Prompt Accuracy scores tell a similar story. Normal application-building tasks were capable enough; complex requirements deserved more verification. That matters because AI mistakes can consume credits, and Base44 explicitly says it does not normally reverse credits used by erroneous AI actions.
Portability is more nuanced. Two-way GitHub sync and code ownership are meaningful improvements, and we would not describe Base44 as a completely closed no-code system. At the same time, its SDK, CLI, hosted backend and platform-specific services mean it remains more managed than a conventional repository-first stack. Teams that consider infrastructure independence a core requirement should examine that architecture before committing a large production system. Public opinion is likewise mixed rather than uniformly positive. Product Hunt’s 4.4 out of 5 from 41 reviews is relevant to the maker audience we care about, but Base44’s tiny G2 sample and the substantially lower 2.8 out of 5 Trustpilot score reduce confidence in treating any single public rating as representative of the entire user base. That disagreement is why our Review Confidence score stayed at 6.0.
Base44 ranked fifth in our October 1, 2026 hands-on evaluation, scoring 7.91 overall. That does not mean the four products above it should automatically be purchased first. Replit Agent finished only 0.05 points ahead and had a substantially different strength profile. Bolt.New ranked below Base44 overall while still edging it in UI/UX quality. Figma Make was far stronger visually but slower in our test. v0 and Lovable produced stronger overall results under our weighting, but they also represent different workflows and priorities.
Pricing reinforces the same need to buy according to use case rather than rank. For most individuals, our default starting point is Starter monthly at $20 after testing Free. It offers enough capability to discover how Base44 behaves on a real project without locking in a year’s payment. Users who already know they need GitHub, model selection or larger production allowances should consider Builder, and annual billing becomes attractive only after that fit has been established.
The decisive question is therefore not whether Base44 is fifth, first or last on somebody else’s list. It is what part of the product-building process you most want AI to remove. If you want an AI system to take a business workflow and rapidly turn it into a functioning, hosted application with UI, data, permissions and logic in one place—Base44’s strengths line up well with that job. If your priority is meticulously controlled visual design, maximum portability or highly complex engineering behavior, our testing gives stronger reasons to examine alternatives before committing.
For Base44, speed and full-stack convenience are the argument; design refinement, complex-logic reliability and managed-platform dependence are the trade-offs.
FAQ
Is Base44 better for building a full application than for designing a visually polished website?
Yes. Base44’s strongest advantage is that it can generate much more than the interface itself, including authentication, permissions, data structures, backend logic, integrations, hosting and deployment. That makes it particularly effective for dashboards, internal tools, CRMs and workflow applications. In our testing, however, its UI/UX and web-design quality scored 7.7, so buyers focused primarily on highly refined visual design may find stronger options elsewhere.
Does Base44 use its own AI model or third-party models?
Both. Base44 introduced Base 1 in June 2026 as its first in-house model for application creation. Independent reporting indicates that Base 1 was developed by fine-tuning an existing open-source foundation model rather than training a frontier model entirely from scratch. Base44 also remains a multi-model platform, with third-party models available alongside Base 1, and users on Builder or higher can manually select models.
Can you export a Base44 app and continue developing it outside the platform?
Partly. Base44 provides two-way GitHub integration on Builder and higher, allowing users to clone projects locally, edit them in a standard development environment and synchronize changes back to Base44. However, Base44 still relies on its own CLI, SDK and managed backend services, so the platform is more portable than a closed no-code builder but less infrastructure-independent than a traditional repository-first development stack.
Why is Base44’s public reputation so mixed across review platforms?
Different review platforms appear to capture very different types of users and experiences. The article recorded 4.4/5 on Product Hunt from 41 reviews, while Trustpilot showed 2.8/5 with hundreds of reviews. Product Hunt is more concentrated around makers, founders and early adopters, whereas Trustpilot includes broader customer-service, billing and support experiences. Because of this disagreement, Base44 received only 6.0 for Review Confidence despite an 8.8 User Rating score in the evaluation.
Which Base44 plan offers the best starting value for most individual users?
The article recommends starting with Free, then moving to Starter at $20 per month for most individual builders. Starter provides 100 message credits, 2,000 integration credits, unlimited apps, code editing and custom-domain support. Builder at $50 per month becomes more appropriate when GitHub integration, manual AI-model selection or heavier production usage is required. Annual billing saves 20%, but the article recommends starting month-to-month until real credit usage is understood.