

Introduction
Claude is one of the best AI systems available for serious, source-heavy writing, but that judgment needs qualification. Its strongest role is not “press a button and publish.” It works best as a researcher, developmental editor, and drafting partner: absorbing a complicated brief, finding the governing idea, organizing evidence, sustaining a line of argument, and revising without losing the piece’s purpose. For long reports, thought-leadership articles, narrative briefs, executive communications, and editorial work that develops through several rounds, Claude is unusually capable. It is less compelling when the priority is instant output, native search-engine optimization, high-volume campaign production, or flawless factual publication without human review.
That broader assessment is why Claude finished first in our internal comparison with an overall score of 9.41/10. The number is the conclusion of our evaluation, not its premise. It reflects what Claude does across the full writing process, the quality of the product around the model, external evidence, public user sentiment, and the limits that still matter in real work. It is also a point-in-time result as of September 22, 2026, not a permanent declaration that Claude is universally better than every alternative.
Anthropic, the company behind Claude, emerged in 2021 as an AI safety and research company led by siblings Dario Amodei, its CEO, and Daniela Amodei, its president. Its cofounding group also included Chris Olah, Jack Clark, Sam McCandlish, Tom Brown, and Jared Kaplan. Anthropic’s early public emphasis was on building large AI systems that were more steerable, interpretable, and reliable a direction that helps explain why control, long-context work, and careful instruction following became central to Claude’s identity. Anthropic’s 2021 announcement confirms the leadership structure and research focus, while an Anthropic cofounder discussion identifies the seven-person group.
Claude itself launched on March 14, 2023, after a closed alpha with partners including Notion, Quora, and DuckDuckGo. Even at launch, Anthropic presented summarization, search, creative and collaborative writing, question answering, and coding as core uses. Claude 3 followed in March 2024 with the Haiku, Sonnet, and Opus tiers, adding stronger visual understanding, instruction following, brand-voice control, and a 200,000-token context window. Claude 4 arrived in May 2025 with extended thinking, parallel tool use, stronger memory workflows, and more precise instruction following.
The product has since moved well beyond a chat box. Claude can search the web, conduct multi-step research, work from project knowledge, use connectors, analyze images and documents, run code, and create editable documents, spreadsheets, slides, PDFs, and interactive artifacts. Anthropic also began unifying its former chat and Cowork experiences in September 2026, with Claude Docs and Claude Slides rolling out in beta to Pro and Max users first. That change matters for writers because the work can increasingly move from evidence to draft to deliverable within one conversation, although the newest creation tools remain too recent to treat as mature.
Anthropic does not publish a reliable figure for individual paying Claude subscribers, so we do not infer one from app downloads, traffic estimates, or revenue. The best verified adoption figures are business measures: Anthropic said in October 2025 that it served more than 300,000 business customers, and in April 2026 that more than 1,000 business customers were each spending over $1 million on an annualized basis. Those figures demonstrate commercial scale, but neither is a subscriber count, and neither tells us how many people use Claude primarily for writing.
Performance
The current Claude: model capability and product experience
As of our reporting cutoff, Claude Opus 5.5 is the newest Opus model. Anthropic released it on September 22, 2026, and makes it available to Claude Pro, Max, Team, and Enterprise users, as well as through its API and major cloud platforms. Anthropic positions Opus 5.5 as the starting point for most demanding knowledge-work tasks, while Claude Fable 5.1 remains its most capable widely released model for the hardest long-horizon reasoning and research. In other words, “latest” and “highest possible capability” are not identical in the current Claude lineup.
Opus 5.5 is especially relevant to writing because Anthropic says it communicates more clearly, follows writing rules more reliably, and produces professional documents with less unnecessary verbosity than Opus 5. Those are vendor claims, not independent proof, and the model was released on our cutoff date, leaving no meaningful body of long-term public testing. We therefore treat Opus 5.5 as the current product reality but rely on older-model evaluations only as supporting evidence, clearly labeled rather than silently transferring every result to the new model. The API price is $4 per million input tokens and $20 per million output tokens; typical users of the Claude app encounter it through plan limits rather than direct token billing.
Current Claude models support context windows of up to one million tokens, depending on the model, with up to 128,000 output tokens on the listed one-million-token models. That capacity can accommodate a large research pack, book-length material, a collection of interview transcripts, or a substantial archive of brand documentation. But capacity is not comprehension. Anthropic’s own context guide warns that accuracy and recall degrade as context grows—a problem often called context rot. A careful workflow still separates authoritative sources from background reading, labels files clearly, and asks Claude to identify evidence before drafting.
What Claude is like across a real writing workflow
Ideation and angle development. Claude is most useful at the beginning when the assignment is still intellectually untidy. Give it a topic, audience, commercial objective, objections, source material, and examples of what the piece should not become, and it tends to surface competing angles rather than immediately collapsing the task into a generic outline. It can distinguish an argument from a topic, identify what a reader must believe by the end, and expose gaps between the evidence available and the conclusion a brief wants to reach. This is a more valuable use than requesting fifty undifferentiated headline ideas.
The limitation is that Claude can make a weak premise sound coherent. Fluency is not market insight. A strategist still has to decide whether an angle is original, commercially relevant, and worth publishing. Our preferred method is to ask Claude first for tensions, unanswered questions, and evidence gaps; only then do we ask for a recommended thesis. That order makes it a thinking partner instead of a confidence machine.
Research and source synthesis. Claude’s paid Research mode can conduct multiple searches, pursue follow-up questions, and combine the public web with connected internal sources such as Google Workspace material. Standard web search also returns direct citations. This makes Claude useful for building a source map, comparing claims, extracting findings from reports, and turning a disorganized document set into an evidence-led brief. The product’s research mode is available on Pro, Max, Team, and Enterprise plans and requires web search to be enabled.
Its best research behavior appears when the user defines a source hierarchy: primary evidence first, credible independent reporting second, and vendor or affiliate material only where appropriate. Without that instruction, Claude may cite a source that technically supports a sentence but does not justify the broader conclusion. It can also smooth disagreement between sources into a false consensus. Every material statistic, quotation, date, product specification, and causal claim should therefore be checked at the linked source before publication. Citations reduce the cost of verification; they do not remove the need for it.
Outlining and long-form structure. This is one of Claude’s clearest advantages. It is good at preserving the relationship among thesis, section purpose, evidence, counterargument, and conclusion across a long document. When supplied with a detailed brief, it usually creates a progression rather than a pile of headings. It can also diagnose structural problems in an existing draft: a delayed thesis, duplicated sections, unsupported transitions, evidence appearing after the conclusion it should establish, or an introduction that promises something the article never delivers.
That strength explains why Claude often feels more like a developmental editor than a template writer. It is especially effective when asked to state the job of each section in one sentence, map each source to a claim, and identify what can be removed without weakening the argument. This is slower than asking for an immediate article, but it produces more defensible writing.
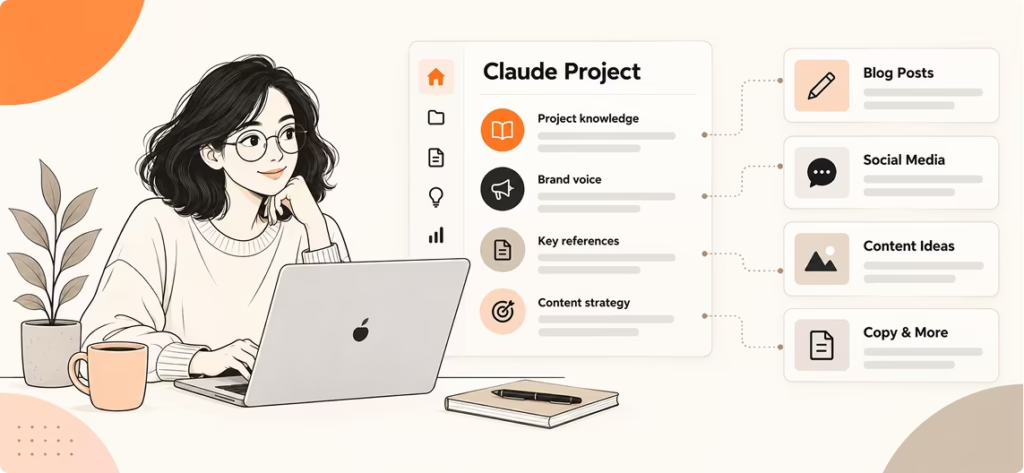
Drafting and voice control. Claude can write clear, connected long-form prose and hold a tone through a substantial draft. Project instructions, account-level instructions, skills, reference samples, and project knowledge can encode audience, vocabulary, stance, formatting rules, prohibited phrases, and brand conventions. Anthropic’s personalization system distinguishes global instructions from project-specific requirements and reusable skills, which is useful when a team has both a general house style and publication-specific rules.
Voice matching is strongest when the reference material is explicit and varied. One sample can cause mimicry; several representative samples help Claude infer stable patterns. We would still avoid telling it merely to “sound human,” which usually replaces one set of clichés with another. Better instructions describe the editorial decisions that create the voice: sentence-length range, degree of directness, use of first person, tolerance for technical language, evidence density, rhythm, and how confidently uncertain claims should be framed.
Once a core piece is sound, Claude is also effective at adaptation: turning a report into an executive summary, a webinar into an article, or a long argument into newsletter, social, sales-enablement, and FAQ versions. The risk is premature repurposing. If the central claim and source base are weak, producing ten channel variants only scales the weakness. We would approve the source document first, then give Claude channel-specific audience and format rules instead of asking it to “shorten this for social.”
Claude’s default prose has recognizable weaknesses. It can over-explain, arrange ideas into overly symmetrical patterns, use polished transitions where a sharper cut would be better, and turn a distinctive position into balanced but less memorable language. In creative fiction, the problem is deeper. A 2026 New Yorker experiment found that iterative prompting could make Claude’s imitations difficult to distinguish from public-domain authors, yet the generated scenes still tended toward atmosphere and stasis rather than consequential human action. That was an informal literary test, not a general benchmark, but it captures an important boundary: stylistic resemblance is not lived perspective or original artistic intention.
Editing and revision. Claude is often more valuable on a strong human draft than on a blank page. It can separate structural editing from line editing, explain why a passage is not working, offer several repair strategies, and preserve intentional quirks when told not to normalize them. It is good at comparing two versions, tracing whether requested changes were actually made, and running a constraint check for length, audience, claims, tone, and formatting after revision.
That strength appeared in a small August 2026 editorial comparison in which a former comedy writer gave Claude, ChatGPT, and Gemini the same draft and coaching instructions. The reviewer preferred Claude’s structural diagnosis and its willingness to leave the creative solution to the author, while finding ChatGPT stronger at line-level rhythm and Gemini easier to apply. One writer and one draft cannot establish a universal ranking, but the test illustrates the role in which Claude tends to add the most value: revealing what the author cannot easily see rather than replacing the author’s choices.
Files, visuals, and finished deliverables. Claude can read common document, spreadsheet, presentation, image, data, notebook, and code formats. It can also create editable files, while Artifacts support interactive documents, visualizations, code, and diagrams. The new Claude Docs and Slides experience reduces the distance between drafting and producing a shareable deliverable. For a content team, this can mean moving from interview notes and data to an article, executive summary, presentation, and supporting table without rebuilding the context in four separate tools.
This is meaningful multimedia support, but it does not make Claude a complete publishing operation. It is not inherently a content-management system, digital asset manager, search-ranking platform, or approval engine. A polished document can still contain weak hierarchy, crowded slides, broken formulas, or unsupported claims. Exported files require visual and functional quality assurance, particularly when client delivery, accessibility, or exact brand layout matters.
Ongoing projects and team use. Projects allow writers to keep source files, instructions, and related conversations together; memory and connectors can reduce repeated setup; Team and Enterprise add collaboration, administration, and security controls. Claude therefore becomes more useful as a maintained editorial workspace than as a sequence of unrelated chats. For sensitive work, plan choice matters: individual plans list model training as opt-out, whereas Team and Enterprise list no training on customer content by default.
The friction is usage. Limits depend on model choice, conversation length, feature use, and task complexity; paid plans have rolling five-hour limits plus weekly limits, and activity across web, desktop, mobile, and Claude Code draws from the same pool. Long source packs, Research, extended thinking, and repeated file creation can consume capacity quickly. Claude is capable of handling a large editorial project, but the subscription tier determines whether the experience feels continuous.
What independent evidence adds
No single benchmark measures “good writing.” The work combines comprehension, factuality, instruction following, argument, voice, presentation, and judgment, so we looked for evidence that tests different parts of the process. The useful question is not whether Claude wins one chart. It is whether independent results point in the same direction as the product-level behavior described above and whether each result measures something relevant to a real editorial workflow.
The strongest direct signal comes from Arena’s blind preference testing. In the September 13 snapshot, Claude Fable 5 ranked first for creative writing, with several other Claude variants near the top. Fable 5 and Fable 5.1 also held the first two positions in the broader writing category. The clustering matters more than the headline rank: it suggests that readers repeatedly prefer Claude outputs for qualities such as voice, structure, and fluency across more than one model configuration. But Arena compares anonymous model responses through head-to-head human votes. It does not test the Claude app’s Projects, Research, citations, file handling, limits, or revision workflow, and preference is not proof of factual accuracy or publication readiness. We therefore use it to support, not manufacture, the 9.9 writing score.
Artificial Analysis supplies a different kind of evidence. Its maximum-effort comparison gives Claude Fable 5.1 an Intelligence Index score of 53, against 47 for GPT-5.6 Sol, across a composite that includes agentic knowledge work, coding, science, long-context reasoning, and other difficult tasks. That breadth is relevant because serious writing often involves more than sentence generation: Claude may need to understand a repository or document set, select tools, recover from a failed approach, and turn evidence into a usable deliverable. The result helps explain our 9.9 intelligence score, but it is not a writing test and should not be read as a six-point advantage in every everyday task.
The same comparison also clarifies the speed penalty. At maximum effort, Claude produced 66 tokens per second versus 82 for GPT-5.6 Sol, and took substantially longer to return its first token and complete a benchmark response. Those figures are measurements of specific API configurations under demanding benchmark conditions, not normal Claude chat latency. They still reveal the trade-off behind our 8.1 speed score: Claude can spend more time and compute reaching a strong answer, while long research, agentic, and file-heavy tasks may also involve searches, tool calls, retries, and checks. For a writer, the relevant measure is time to an accepted deliverable, not how quickly the typing animation begins.
A 2025 Washington Post test used 115 questions and expert judges. Claude led overall without hallucinating; no system exceeded 70%. Results varied by domain. That supports Claude’s strength in document analysis while also showing why domain performance and human review matter.
Public app feedback adds a different warning. A July 2026 preprint analyzing 17,012 English-language reviews found Claude’s sentiment unusually polarized. The paper remains under peer review, and app-store reviews primarily describe the whole consumer experience—including access, reliability, limits, and subscriptions—rather than controlled writing performance. Its value is precisely that distinction: a strong model can coexist with substantial product frustration.
Why our score is 9.41/10
Only after considering the overall workflow do the component scores make sense. Our framework asks seven different questions: can Claude reason through the work; can it finish efficiently; is the writing good; does it follow the brief; are users satisfied; how much confidence should we place in those reviews; and does the surrounding product make the capability usable? Writing quality carries the largest weight at 25%, followed by prompt accuracy at 20%. Intelligence and features each contribute 15%, speed and user rating 10% each, and review confidence 5%. That weighting rewards an accepted deliverable rather than a dazzling first paragraph.
The weighted calculation is 9.41/10. It is our point-in-time editorial assessment, not a universal benchmark or a claim that every Claude model, plan, and prompt will perform identically.
| Evaluation Factor | What It Measures | Weight |
|---|---|---|
| AI Intelligence | Evaluates architectural reasoning, debugging, context retention, tool use, planning, and recovery. | 15% |
| Speed | Measures delivery speed and consistency, including retries, tooling, tests, and revisions. | 10% |
| Writing and Content Creation Quality | Originality, coherence, style, consistency, factual grounding, adaptability, and multimedia support. | 25% |
| Prompt Accuracy | Instruction compliance, completeness, source fidelity, tone, constraints, and revision reliability. | 20% |
| User Rating | Weighted public satisfaction from credible review platforms | 10% |
| Review Confidence | Combines authenticity, sample size, recency, relevance, diversity, and model-version confidence. | 5% |
| Features & Usability | Evaluates UX, workflows, research, collaboration, integrations, governance, accessibility, and setup burden. | 15% |
The arithmetic is transparent: (9.9 × 15%) + (8.1 × 10%) + (9.9 × 25%) + (9.7 × 20%) + (9.2 × 10%) + (8.3 × 5%) + (9.1 × 15%) = 9.41.
The weighted score is high because Claude performs unusually well on the factors we consider most consequential for deep writing: intelligence, writing quality, and prompt accuracy. Its lower speed, review-confidence, and usability scores are not footnotes; they explain why the overall result is 9.41 rather than something closer to 10.
Comparisons Before You Buy
Claude’s first-place result is narrow. ChatGPT scored 9.36, only 0.05 points behind, which is not a decisive quality gap. The more useful buying question is where each product places its strength.
| Product | Overall Score | AI Intelligence | Speed | Writing/ Content Quality | Prompt Accuracy | User Rating | Review Confidence | Features & Usability | Best For |
|---|---|---|---|---|---|---|---|---|---|
| Claude | 9.41 | 9.9 | 8.1 | 9.9 | 9.7 | 9.2 | 8.3 | 9.1 | Deep Writing Work |
| ChatGPT | 9.36 | 9.6 | 8.9 | 9.2 | 9.4 | 9.2 | 8.9 | 9.9 | For research, drafting, editing |
| Gemini | 9.17 | 8.9 | 9.6 | 9.4 | 8.8 | 8.8 | 8.2 | 9.8 | Google Workspace users |
| Jasper | 8.90 | 7.6 | 8.7 | 8.9 | 9.3 | 9.4 | 8.8 | 9.5 | Brand Campaign Teams |
| Grammerly | 8.73 | 7.0 | 9.8 | 8.8 | 8.8 | 9.4 | 9.3 | 8.9 | Writing Quality Teams |
| Writesonic | 8.63 | 7.4 | 8.4 | 8.6 | 8.8 | 9.4 | 9.0 | 9.2 | Students, non-native English writers, and Proofreaders |
Claude versus ChatGPT
This is the closest comparison. Claude has the edge in our methodology when a project depends on reading a large body of material, developing a coherent argument, preserving the logic of a long draft, and responding to detailed editorial constraints. ChatGPT is the stronger default when a buyer wants one assistant spanning research, writing, data work, image generation, interactive tools, and broad agentic execution. OpenAI’s current research tools can work across the web and connected apps, while projects and canvas support sustained drafting.
The score difference is too small to justify switching on its own. A team should test the same real brief in both systems, using the same sources, constraints, and revision requests. Claude is our preference for deep editorial work; ChatGPT may be the better organizational standard when breadth and tool consolidation matter more than Claude’s writing advantage.
Claude versus Gemini
Gemini’s advantage is workflow placement. Google’s paid AI plans integrate Gemini into Gmail, Docs, and other Google products, so Workspace users can draft, summarize, and organize without repeatedly moving context between services. Claude is stronger in our evaluation for nuanced long-form development and prompt fidelity, but Gemini may save more time in an organization where source documents, review comments, email, and publication drafts already live in Google Workspace. Integration fit can outweigh a modest model-quality difference.
Claude versus Jasper, Grammarly, and Writesonic
The specialist products answer narrower operational problems. Jasper centralizes brand voice, audiences, style guidance, product knowledge, and campaign workflows; it is easier to govern when many marketers must produce coordinated assets from the same brief. Its campaign tools are designed around repeatability and brand control rather than open-ended reasoning.
Grammarly is less capable as a research or deep-drafting environment, but it meets writers inside existing applications with sentence-level corrections, tone guidance, rewrites, brand tones, and style rules. For a company trying to improve everyday communication across a large workforce, that ambient assistance can be more valuable than asking everyone to adopt a separate AI workspace.
Writesonic focuses more directly on structured article production, keyword research, internal linking, citations, brand voice, and SEO or generative-engine optimization. That can make it a more practical production tool for search-led teams, even though Claude is the stronger general reasoner and editor in our assessment.
What Claude’s public rating tells us
Claude has no single “true” public rating. In our September 22 research, legitimate Claude scores ranged from 1.5/5 to 5.0/5. That spread is not a reason to select the most flattering number or to average everything together. It is evidence that the platforms are observing different parts of the relationship. An app store is heavily influenced by mobile reliability and access. An open consumer site is more likely to capture billing, support, and cancellation disputes. A launch-oriented community has its own enthusiasm and selection effects. A professional software marketplace is closer to the question this article asks: how well does Claude function as a work product for research, writing, documents, and repeat use?
| Product | Source used | Public Rating | Votes & Reviews |
|---|---|---|---|
| Claude | Google Play Store | 4.4/5 | 747K+ reviews |
| ChatGPT | Google Play Store | 4.5/5 | 61.3M+ reviews |
| Gemini | Google Play Store | 4.4/5 | 46.6M+ reviews |
| Jasper | Capterra | 4.8/5 | 1.8K+ reviews |
| Grammerly | G2 | 4.7/5 | 14K+ reviews |
| Writesonic | Trustpilot | 4.6/5 | 6K+ reviews |
For that reason, G2 is the sole numerical source for Claude’s User Rating in our scorecard. Our frozen September 22 capture recorded 4.6/5 from 468 reviews on the G2 category. The sample is large enough to reveal repeated professional experience without pretending to represent every free, mobile, or API user. More importantly, G2 provides work context around reviewers and applies visible authenticity controls: it verifies identity, checks submissions algorithmically, and manually reviews them before publication. It labels incentivized reviews and says incentives are not conditional on positive sentiment. Those safeguards do not make every opinion correct, but they make the source more decision-useful for this particular evaluation.
We did not blend G2 with Claude’s ratings on Google Play, Apple’s App Store, Trustpilot, Capterra, Product Hunt, TrustRadius, or smaller software communities. Combining those numbers would mix unlike audiences, collection methods, rating behavior, product surfaces, and periods of use. It could also count the same person more than once. Those sources still have value: taken together, they show that satisfaction changes sharply with context and they help us look for recurring strengths or complaints. They corroborate the analysis; they do not enter the 9.2 calculation.
The separate 8.3 Review Confidence score answers a harder question: how much trust should we place in the 9.2? Our heuristic gives 30% of that judgment to authenticity and moderation, 25% to sample size on a logarithmic scale, 20% to recency, 15% to relevance to the current product and model, and 10% to source diversity and corroboration. G2 performs well on moderation, professional relevance, and sample size, while Claude’s broader review footprint gives us useful cross-checks.
Confidence stops at 8.3 because even a genuine review does not identify a controlled test condition. Reviewers self-select; some reviews are incentivized; paid and free plans expose different limits; and a review may refer to an older interface or model. Claude changes quickly enough that a detailed review can remain authentic while becoming less representative of the product a buyer receives today. The distinction is important: 9.2 describes the observed level of professional user satisfaction; 8.3 describes the strength and current relevance of the evidence behind it.
Which Claude plan is worth buying?
The Free plan is sufficient to test Claude’s voice, basic web search, file handling, memory, and Artifacts against your own work. It is not the right basis for judging sustained professional use because Research, access to more models, broader project work, and higher capacity sit on paid plans.
For most individual writers, editors, researchers, and content strategists, Pro is the correct starting point. It costs $20 month-to-month or $200 paid annually, equivalent to about $16.67 per month and a $40 annual saving. Pro includes more usage, Research, Projects, additional models, Claude Docs and Slides, Claude Code, and Microsoft 365 access. The pricing page lists these inclusions and notes that limits still apply.
Our recommendation is to buy one month of Pro first. Run actual assignments, not demo prompts, through ideation, research, drafting, two revision rounds, and final export. If Claude becomes a weekly part of the workflow and the capacity is sufficient, switch to the $200 annual plan. The annual discount is worthwhile only after fit is proven; paying for a year does not improve model quality or remove limits.
Max 5x at $100 per month and Max 20x at $200 per month are monthly-only plans for people who use Claude throughout the day and repeatedly hit Pro’s capacity. They buy more usage, higher output limits, priority access, and earlier access to features, not five or twenty times better writing. Teams of two to 150 should consider Team, at $25 per standard seat monthly or $20 per seat per month billed annually; premium seats are $125 monthly or $100 per month annually. Enterprise begins at $20 per seat per month billed annually plus usage at API rates and adds deeper security and administration.
Conclusion
Claude earns our 9.41/10 because it is the strongest product in this comparison for deep writing work: understanding difficult material, finding the argument inside it, building a coherent structure, drafting with control, and improving a piece through substantive revision. Its value is greatest when the writer brings judgment, sources, and a clear editorial standard, not when the goal is to automate authorship completely.
Its central strength is sustained editorial intelligence. Its central limitation is that polished language can disguise weak evidence, generic choices, or factual error, while deep workflows can be slower and more capacity-intensive than the interface first suggests. Every important output still needs a human owner who checks sources, protects voice, and decides what is worth saying.
Choose ChatGPT if broad tool coverage and general-purpose workflow consolidation matter most; Gemini if Google Workspace integration is decisive; Jasper for governed campaign production; Grammarly for inline organization-wide writing support; or Writesonic for search-led content operations. Choose Claude when the difficult part is thinking through the writing itself.
For most individual professionals, start with Pro month-to-month, test it on real work, and move to the annual Pro plan only after it proves useful. That is the most balanced way to buy Claude: enough access to evaluate its real strengths, without confusing a high score or a polished first draft with certainty.
FAQ
Is Claude’s 9.41/10 score mainly driven by its writing style, or by the full writing workflow?
The 9.41/10 score reflects much more than polished prose. Writing and content creation quality carries the largest single weight at 25%, but prompt accuracy contributes 20%, while intelligence and features each contribute another 15%. Speed, user rating, and review confidence make up the rest. That means Claude scores highly because it can handle the broader process around serious writing: understanding large source sets, developing an argument, following detailed editorial constraints, revising structurally, and producing usable deliverables. Its lower scores for speed and review confidence also prevent the final rating from simply rewarding impressive output quality.
Why can Claude’s newest model be different from its most capable model?
The article distinguishes between the newest release and the model offering the highest overall capability. At the September 22, 2026 cutoff, Claude Opus 5.5 was the newest Opus model, while Claude Fable 5.1 remained Anthropic’s most capable widely released option for the hardest long-horizon reasoning and research tasks. That distinction matters because buyers often assume the newest model is automatically the best choice for every workload. In practice, model selection can depend on whether the task prioritizes demanding reasoning, writing quality, speed, availability, or usage limits.
Can Claude be trusted to research and write an article without fact-checking afterward?
No. Claude can substantially reduce the work involved in research, but the article does not treat citations as a substitute for verification. Its Research mode can conduct multiple searches, follow leads, combine public-web research with connected sources, and help organize evidence into a usable brief. The risk is that Claude can cite a source that supports part of a sentence while the broader conclusion goes further than the evidence allows, or it can smooth genuine disagreement between sources into apparent consensus. Material statistics, quotations, dates, specifications, and causal claims should therefore still be checked at the original source before publication.
When does Claude’s one-million-token context window actually help a writer?
The large context window is most useful when the writing task depends on a substantial body of material: research reports, interview transcripts, long manuscripts, brand documentation, or a large project archive. It allows more of that material to remain available within the same working context. But the article makes an important distinction between capacity and comprehension. Anthropic itself warns that recall and accuracy can deteriorate as context grows. For serious work, writers should still separate authoritative sources from background material, label files clearly, and have Claude identify the evidence it intends to use before drafting.
What would justify paying for Claude Max instead of staying on Pro?
Writing quality alone is not the reason to upgrade. The article recommends Pro as the starting point for most individual writers, editors, researchers, and content strategists because it already includes higher usage, Research, Projects, additional models, Docs and Slides, Claude Code, and other professional features. Max becomes relevant when someone uses Claude heavily throughout the day and repeatedly runs into Pro’s capacity limits. The higher-priced Max tiers primarily buy more usage, higher output limits, priority access, and earlier access to features; they do not provide five or twenty times better writing.